Speech Synthesis for AI Human
Deep Learning and Speech Processing based Projects
Deep Learning and Speech Processing based Projects
Natural Language Processing and Machine Learning based Projects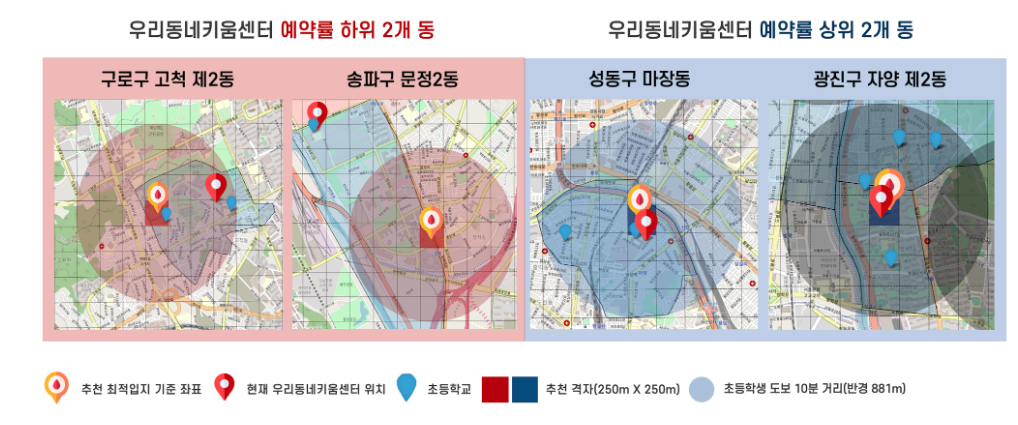
Data Preprocessing Tools based on Java and Python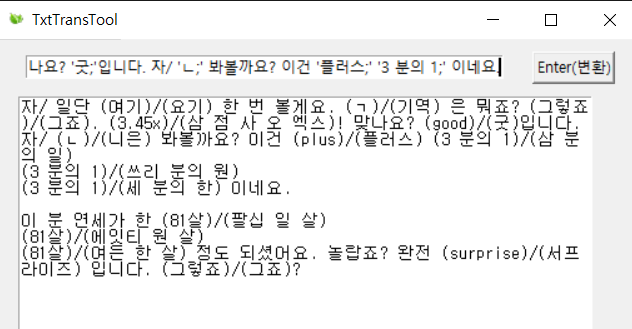
Integrated Multimodal Prompt and Control for Emotional TTS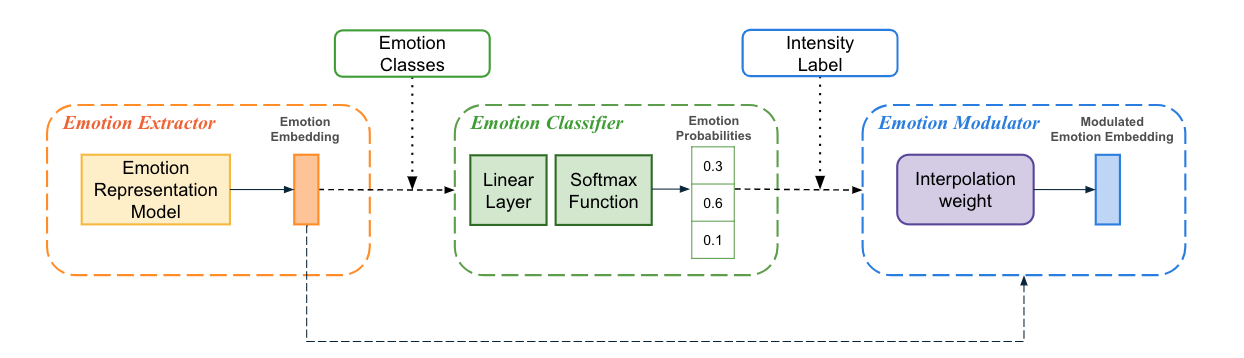
Published:
📝 Paper: Conv-TasNet: Surpassing Ideal Time-Frequency Magnitude Masking for Speech Separation
Published:
📝 Paper: Glow: Generative Flow with Invertible 1x1 Convolutions
Published:
📝 Paper: AUTOVC: Zero-Shot Voice Style Transfer with Only Autoencoder Loss
Published:
📝 Paper: wav2vec: Unsupervised Pre-training for Speech Recognition
Published:
📝 Paper: vq-wav2vec: Self-Supervised Learning of Discrete Speech Representations
Published:
📝 Paper: Survey on Deep Neural Networks in Speech and Vision Systems
Published:
📝 Paper: Glow-TTS: A Generative Flow for Text-to-Speech Synthesis
🔍 Summary: This paper introduces a flow-based model for TTS, improving robustness compared to Tacotron.
Published:
📝 Paper: wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations
Published:
Published:
📝 Paper: PortaSpeech: Portable and High-Quality Generative Text-to-Speech
Published:
📝 Paper: YourTTS: Towards Zero-Shot Multi-Speaker TTS and Zero-Shot Voice Conversion for everyone
Published:
📝 Paper: Neural Grapheme-to-Phoneme Conversion with Pre-trained Grapheme Models
Published:
📝 Paper: Automatic Prosody Annotation with Pre-Trained Text-Speech Model
Published:
📝 Paper: Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers