About Me
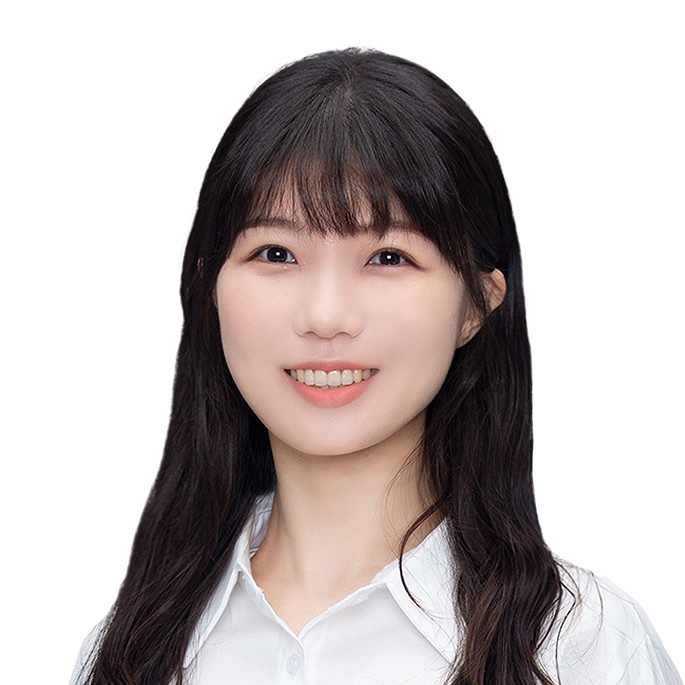
Hello! I’m Jaeyoung Shin, an M.S. student in Artificial Intelligence at Music and Audio Research Group supervised by Professor Kyogu Lee at Seoul National University. Previously, I worked as an AI Research Engineer specializing in expressive speech synthesis, multilingual TTS, and multimodal generative models.
I have contributed to voice cloning, expressive TTS, and audio quality assessment at GenesisLab and PuzzleAI.
What I Do
My research focuses on making speech AI more expressive, natural, and robust. Key areas of expertise include:
- Expressive Speech Synthesis – Enhancing emotional and prosodic quality in AI-generated speech.
- Multimodal AI – Integrating text, speech, and vision to improve generative models.
- Speech Enhancement & Retrieval – Improving audio quality and assessment using deep learning.
Research & Experience
Originally majored in marine biology, I transitioned into AI research after discovering the potential of deep learning in cognitive neuroscience and speech technology.
- AI Scientist at GenesisLab – Developed voice cloning, expressive TTS, and chatbot programs using LLMs.
- AI Researcher at PuzzleAI – Focused on speaker verification, real-time noise reduction, and document summarization.
- Intern at TmaxSoft – Created a Python tool that doubled text preprocessing efficiency.
- Undergraduate Intern at Computational Cognitive Affective Neuroscience Laboratory, IBS – Applied fMRI analysis, deep learning, and signal processing to study brain responses.
Current Focus
I’m currently working on an automatic audio quality Assessment and a multimodal emotional TTS system designed to overcome low-resource constraints. Additionally, I have recently developed an interest in music AI. Lastly, I have been continuously exploring AI safety research to ensure generative models remain trustworthy and ethical.
Contact
I welcome opportunities to discuss my research and collaborations in Audio AI and deep learning.
📌 GitHub | LinkedIn | CV |